
Google data agent kit automates fraud review pipeline
Tue, 27th Oct 2026 (Today)
Google has outlined a workflow for building a fraud review pipeline with its Data Agent Kit. The setup links data ingestion, model training and orchestration inside an IDE.
The toolkit lets coding agents and Visual Studio Code-based environments work with Google Cloud data services from within the editor. In Google's published example, a data scientist uses the software to process transaction logs, train a fraud model and send higher-risk records to a review queue.
At the start of the workflow, raw JSON transaction logs stored in Google Cloud Storage are loaded into BigQuery through a generated PySpark notebook. Users can review the notebook code and run it on a preconfigured Spark Serverless runtime, then inspect the resulting BigQuery table and its metadata inside the IDE.
The next step prepares the records for analysis by removing duplicate entries and separating incomplete data. This process is placed in a dbt project, which creates staging and enriched tables in BigQuery and runs a transaction uniqueness test.
The enrichment step joins valid transaction records with payer and payee reference data while preserving the is_fraud label used for model training. Records with missing transaction IDs are placed in a separate invalid_transactions table.
Model training
Once the data is prepared, the workflow uses another generated PySpark notebook to train a Random Forest classifier on the enriched transaction table. The model is trained only on records where the fraud label is known, with categorical features encoded, amounts scaled and performance assessed using ROC AUC.
The trained model is then saved to Google Cloud Storage. Users can verify in the IDE that the model artefacts have been written to storage before moving on to inference.
Batch scoring is carried out on transactions in the enriched table that do not yet have an is_fraud value. In Google's example, records with a fraud probability score of at least 0.50 are written to a Spanner table called SparkEvalFraudReviewQueue in a database used for fraud review.
That table becomes the list for a compliance team to examine. The process does not determine whether fraud has occurred, but creates a ranked set of transactions for further investigation.
Daily pipeline
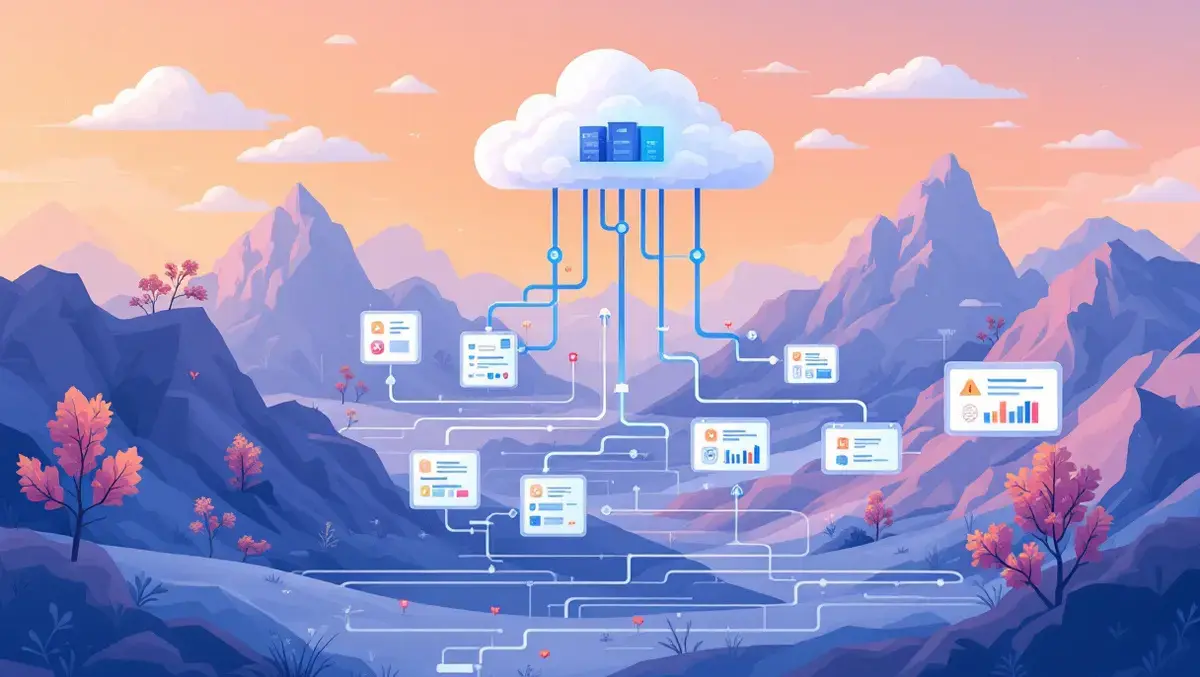
Google also described how the separate stages can be linked into a scheduled workflow using Managed Service for Apache Airflow. The orchestration pipeline runs ingestion, dbt transformations and batch inference in sequence, and is scheduled to run daily at midnight.
According to the description, the agent generates both a YAML pipeline definition and deployment configuration. The definition sets task dependencies and timing, while the deployment settings identify the Airflow environment where the workflow will run.
Data Agent Kit then converts that definition into an Airflow DAG that can be inspected as an interactive graph in the IDE. Users can open the pipeline, review individual tasks, follow links back to notebook code and monitor execution history, including task status, duration and logs.
The approach reflects a broader push by cloud providers to bring more data engineering and machine learning work into coding environments already used by developers and analysts. By combining notebook generation, dbt project creation and orchestration in one interface, Google is trying to reduce the number of separate tools involved in moving data from source systems to operational review queues.
The example also shows Google's emphasis on integrating several of its own services into a single workflow, including Cloud Storage, BigQuery, Spark Serverless, Spanner and Airflow. In this case, the result is an automated daily process that takes raw payments data through cleansing, modelling and prioritisation for human review.
Airflow runs the pipeline daily, taking new batches of data from raw logs to the review queue.